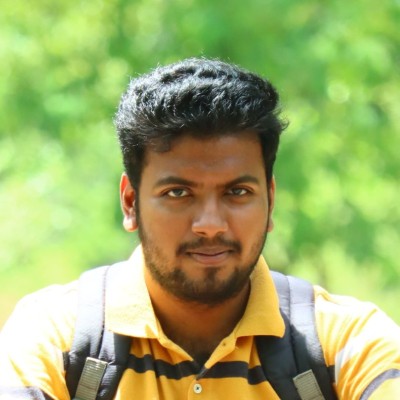
I build agentic workflows, retrieval systems and multimodal AI applications. At Staple AI, I own engineering delivery for 20+ enterprise customers. I personally implement approximately 80% of the requirements for my customer portfolio, from architecture and code to testing, rollout and production support.
Based in India · Remote opportunities with global teams
I take customer requirements through discovery, solution design, code, testing and rollout. I personally build features, integrations, migration tools and production fixes, alongside customer telemetry, dashboards and agents for adoption decisions.
Follow synthetic customer telemetry through retrieved playbooks, a proposed action, human approval and recovery after a simulated tool failure. Run the dashboard locally and inspect each decision.
16 declared synthetic scenarios exercise 106 control checks, including lost-response recovery and rejected actions.
One-command local setup with Python's standard library; no credentials or paid APIs.
Scripted planner replay and lexical retrieval, with synthetic data. Demonstrates orchestration controls; it does not measure live LLM performance or represent employer work.
Upload an image, choose physical page dimensions and receive a generated PDF. A small, inspectable example of request validation, resource handling and repeatable API tests.
25 tests covering PDF output, invalid input, resource limits, concurrency and cleanup.
GitHub Actions runs on Python 3.11, 3.12 and 3.13.
Local setup, sample request and API response contracts are documented; no credentials are required.
Earlier personal project, with reliability improvements added in October 2026. Demonstrates API engineering; it is not an AI model or a hosted production service.
Public summaries of my contributions at Staple AI. Customer data and employer source code remain private; each case identifies its delivery stage and my scope.
Showing case study: Enterprise delivery
STAPLE AIProduction launch · April 2025
Bringing complex-table extraction into production.
Table extraction needed more than a model response: the result had to map back to the original document, fit existing APIs and behave consistently across regions.
Design choice
Keep extracted cells tied to page-specific OCR coordinates so model output can be checked against the source document.
01Extract
OCR and vision-language output
02Map back
Extracted cells → source boxes
03Structure
Table schema and scan pipeline
04Observe
Tracing and failure boundaries
Engineering decisions
Benchmarked OCR and vision-language approaches, comparing extraction behavior, cost and layout handling before selecting the integration approach.
Built Python model-service APIs, table schemas, templates and OCR-coordinate mapping; integrated the feature into the scanning pipeline with other engineers.
Followed the launch with bounded mapping timeouts, configurable matching thresholds, multilingual normalization and model-routing controls.
Outcome & scope
Shipped complex-table extraction across three services and three regions, connecting applied model research to APIs, data contracts and production operations.
My work: model benchmarking, Python APIs, table schemas, source-coordinate mapping and cross-service integration. The production launch was a team effort.
Failure modes & verification +
A plausible cell mapped to the wrong source text
Keep source-page coordinates attached to extracted cells; use configurable matching thresholds and multilingual normalization during mapping.
Mapping work delays the scan pipeline
Bound mapping with timeouts and expose model-routing controls so extraction behavior can be investigated independently of the surrounding services.
Production integration across three services and three regions. Model benchmarking informed the implementation; no public accuracy or latency benchmark is claimed.
A promising model response is not enough to justify a release. Quality, repeatability and cost need to be compared against the same reference data.
Design choice
Compare field quality, repeated-run agreement and token cost on shared ground truth to make model-selection tradeoffs visible.
01Reference
Documents and editable ground truth
02Run
Shared inputs across providers
03Compare
Fields, consistency and cost
04Review
Evidence for a model decision
Engineering decisions
Built a Next.js and FastAPI evaluation platform with bilingual ground-truth editing, per-field similarity and F1, live progress and provider cost accounting.
Connected eight providers and 25 models, with repeated-run consistency checks and review thresholds to support model-selection decisions.
Added stop-run handling with partial results, production-compatibility checks and self-hosted provider support before the staging handoff.
In a separate template-retrieval research workstream, evaluated multimodal embeddings and Milvus retrieval, filtering, upsert and deletion; co-designed validation using header, position and vector checks.
Outcome & scope
Delivered an internal evaluation dashboard spanning eight providers and 25 models, making field quality, consistency and token cost visible in one workflow.
My work: requirements, platform design, FastAPI backend and Next.js review interface through staging handoff. Template-retrieval evaluation and validation design were a separate research workstream.
Failure modes & verification +
A strong example hides inconsistent field quality
Run shared inputs against editable ground truth, compare per-field similarity and F1, and repeat runs to inspect agreement.
A cancelled evaluation loses useful work
Keep partial results when a run stops, with live progress and cost accounting available to the reviewer.
Research results are mistaken for a deployed retrieval system
Keep the embedding and Milvus work identified as a separate research stream; the dashboard deliverable ended at staging handoff.
Internal platform delivered through staging handoff. The eight-provider, 25-model scope describes integration coverage, not a measured quality win or production rollout.
Changing the transport without breaking the contract.
Moving document processing from synchronous calls to messaging changes delivery, retry and recovery behavior. Existing scan outputs still need to remain compatible.
Design choice
Acknowledge messages after storage and pair bounded retries with message-ID deduplication to limit duplicate work during recovery.
01Queue
Route work and deduplicate messages
02Process
Generate, store and acknowledge
03Recover
Bounded retries and dead-letter queue
04Compare
Reference scan-message fixtures
Engineering decisions
Co-developed the event-driven specification and implementation with acknowledgement after storage, bounded retries, message-ID deduplication and dead-letter routing.
Built scan-message generation and PDF rendering changes, checking output against 12 reference fixtures produced by the existing service.
Prepared a reviewer walkthrough, release lineage and rollout checks, including queue-delivery settings and trace propagation.
Outcome & scope
Delivered the migration through a staging release with compatibility checks across 12 scan-message reference fixtures.
My contribution: messaging design, implementation, scan-message compatibility and release preparation alongside another engineer, through staging validation against 12 reference fixtures.
Failure modes & verification +
A retry repeats already completed work
Use message-ID deduplication and acknowledge only after storage; apply bounded retries and dead-letter routing.
A transport change silently changes scan output
Compare generated scan messages against 12 reference fixtures from the existing service before the staging release.
A failed job is hard to follow across workers
Include trace propagation and queue-delivery settings in the reviewer walkthrough and rollout checks.
Collaborative migration delivered to staging. The checks establish compatibility for the reference fixtures; they do not establish exactly-once delivery or a production throughput result.
Shared databases and asynchronous workers make it difficult to understand load and trace a document across service boundaries.
Design choice
Route suitable reads through separate replica sessions while keeping writes on the primary, and log the route for verification.
01Route
Read replica or primary write
02Connect
Explicit engines and sessions
03Trace
Context across worker boundaries
04Investigate
Linked logs, metrics and spans
Engineering decisions
Separated primary and replica endpoints, engines and sessions across six or more services, using FastAPI dependencies and repository-level routing.
Tuned connection pooling and added read/write logging so database access followed the intended route.
Added trace-context middleware, logging bridges and metrics to follow model-processing work through asynchronous services.
Outcome & scope
Moved read traffic off primary databases across six or more services and added connected tracing for model-processing workflows.
My work: service-level database routing, connection-pool configuration and observability integration.
Failure modes & verification +
Reads and writes use an unintended connection
Make primary/replica engines and sessions explicit in dependencies and repositories; inspect read/write route logs.
Worker boundaries break an incident trace
Propagate trace context through middleware and logging bridges, connecting model-processing logs, metrics and spans.
Service-level routing and observability across six or more services. These changes demonstrate implementation scope; no measured database speedup or recovery-time reduction is published.
STAPLE AICustomer engineering across SDE and FDE roles
Take customer requirements through delivery and adoption.
Customer requests, production failures and usage patterns need to become clear engineering work, with a way to verify the result and support adoption.
Design choice
Use reproducible cases, baseline snapshots and dry-run checks to scope production changes and verify recovery against the customer workflow.
01Discover
Requirements and customer context
02Build
Personally code features, integrations and fixes
03Verify
Baselines, QA and recovery checks
04Support adoption
Usage telemetry, dashboards and agents
Engineering decisions
Own technical discovery and engineering delivery for 20+ enterprise customers. Personally design, code, test and roll out customer features and integrations, collaborating with product, engineering and customer success on shared dependencies.
Use document comparisons, replay tools and logs to separate model, data and code defects; build reproducible cases before choosing the fix.
Build migration baselines, staged rollout plans, export-parity checks and rollback procedures. Lead incident recovery with transactional repairs, dry-run tools and post-recovery verification.
Build AI dashboards and agents around customer telemetry to surface usage patterns, support adoption discussions and identify usage-growth and upsell opportunities.
Outcome & scope
Restored stalled ingestion, recovered missing source files and delivered customer model migrations. Verified each result against the affected customer workflow.
I personally implement approximately 80% of the requirements for my customer portfolio, from solution design and code to testing, rollout and verification. This includes customer migrations, incident recovery and telemetry-based adoption support.
Failure modes & verification +
The proposed fix addresses the symptom instead of the cause
Compare source documents, replay behavior and logs to distinguish model, data, configuration and code defects.
A migration changes customer-visible output
Capture baseline snapshots, run dry-run checks, compare export parity and prepare rollback before staged changes.
Recovery finishes without proving the workflow works
Use transactional repairs and post-recovery verification against the affected customer workflow.
Scope spans multiple customer engagements. Telemetry dashboards and adoption agents support customer decisions; revenue or adoption uplift is not quantified here.
Core engineer for complex-table extraction shipped across three services and three regions. Benchmarked OCR and vision-language approaches, built the model-service APIs, and connected model output back to source coordinates.
Multimodal AI
OCR + VLMs
Model integration
02
Evaluation that guides model changes
Built an internal LLM/VLM evaluation dashboard spanning eight providers and 25 models, with field-level comparison, consistency checks and cost visibility. Built API regressions across 70 endpoints with contract checks, cleanup and region-aware CI.
LLM / VLM evaluation
Regression testing
GitHub Actions
03
AI platforms with observability and recovery
Co-developed an event-driven document-processing migration through a staging release, with queues, retries, dead-letter routing and idempotency. Added distributed tracing and separated database read/write traffic across six or more services.
RabbitMQ
OpenTelemetry
Database design
04
Customer telemetry and adoption agents
Personally design, code, test and deliver solutions for 20+ enterprise customers, from discovery and migrations to verified recovery. Build dashboards and AI agents around customer telemetry to support adoption and identify usage-growth and upsell opportunities.
Enterprise delivery
Customer telemetry
Production recovery
02
Experience
Engineering, teaching and the communities where I started building.
Enterprise AI · Product engineering · Customer delivery
Own customer requirements end to end for 20+ enterprise customers: personally design, implement, test and roll out AI features, integrations and production fixes, with ongoing adoption support.
AI Software Engineer · SDE-2From May 2025 · Earlier role
AI Software Engineer · SDE-1From May 2024 · Earlier role
Responsibilities & technical work+
As an FDE, turn discovery findings into working implementations: write code, build integrations and migration tools, test the changes, handle rollout and verify customer workflows. Collaborate with product, engineering, customer success and QA on shared dependencies.
Build AI dashboards and agents around customer telemetry to surface usage patterns, support adoption discussions and identify upsell opportunities.
As a core product engineer, took complex-table extraction from OCR/VLM research to production across three services and three regions, building model APIs, templates and coordinate mapping.
Built an eight-provider, 25-model evaluation dashboard and a regression platform covering 70 gateway API endpoints. Moved monitor scheduling to GitHub Actions while retaining Postman CLI for execution.
Co-developed asynchronous document processing with RabbitMQ, dead-letter queues, idempotency and compatibility fixtures. Delivered the migration through a staging release.
Delivered enterprise model migrations with baseline snapshots, rate-controlled writes, post-write verification and export-parity checks.
Built China-region OCR integrations, multilingual normalization, strict/fuzzy vendor matching and configurable model routing. Added tracing, timeout boundaries and separate database read/write pools.
Wrote production root-cause analyses, engineering runbooks and shared QA/migration procedures; reviewed code and mentored junior engineers.
Built a shared Python library for telemetry, database and S3 integration, backed by 165 tests; compared document-AI products on a shared sample to inform product recommendations.
Frame-by-frame detection of disruptions in CCTV footage, including blur, black screens and freezing.
Computer vision
Video analytics
Geometric analysis
Inside the build+
Built heuristic checks for blank frames, blur, lag, freezing and quality degradation; interval reports cover blank, blur and lag, with quality and freezing exposed as summary scores.
Generated Excel and JSON reports with disruption start/end timestamps, type and score.
An API that converts uploaded photos and page dimensions into downloadable PDF layouts.
Python
FastAPI
Pillow
FPDF
Inside the build+
Built an image-processing backend with FastAPI, Pillow and FPDF.
Exposed a workflow for image uploads, page-layout dimensions and generated PDF output.
Added 25 repeatable tests for PDF output, request validation, resource limits, concurrent requests and cleanup; GitHub Actions runs the suite on Python 3.11–3.13.
Bachelor of Engineering · Computer and Electrical Engineering
Alongside my degree: the IEEE Computer Society, Team AutoZ and TIFAC projects, plus student tools, machine-learning experiments and competitions.
HIGHER SECONDARY · MPC
Sree Vidyanikethan
Tirupati, India
SECONDARY EDUCATION
Bharatiya Vidya Bhavan’s
High school
08
A little more about me
I’m comfortable moving between a customer conversation, a system design decision and the code that makes it work.
My 5+ years of experience span technical teaching, internships and engineering roles. I started with teaching Python and working on machine-learning projects. It grew into AI applications, agentic workflows and enterprise delivery. Teaching still shapes how I work: make the problem understandable, examine the assumptions, and explain the decision.
I enjoy working on the whole problem. That can mean building an API, tracing a production issue, automating a repetitive workflow, or helping someone use a product well.
AWAY FROM THE KEYBOARD
Swimming. Flying drones. Following the next idea.
09
LET’S HAVE A CONVERSATION
Let’s talk about what you’re building.
For forward deployed engineering, agentic AI applications and senior AI platform roles. Open to full-time remote roles and selected contract projects with international teams.